


Itzert.com hat nicht so viele Fragen und Antworten wie andere Unternehmen. Alle unserer Produkte sind preisgünstig. Prüfungsmaterialien von Itzert.com beinhalten fast alle Schwerpunkte der Prüfung. Falls Sie bei der Prüfung durchfallen, nachdem Sie unsere Prüfungsmaterialien benutzt haben, werden Sie eine volle Rückerstattung von uns bekommen. Solange Sie unsere Fragenkataloge sorgfätig studieren, werden Sie die Prüfung 100% bestehen.

Heutzutage ist Snowflake DSA-C03 Zertifizierungsprüfung sehr beliebt. Es kann auch die Fähigkeit eines Fachmannes messen. Mit dem Zertifikat von Snowflake Certified Engineers werden Sie sicherlich eine bessere Arbeit und eine schönere Zukunft haben.
Es wird nie schneller oder einfacher, dass man die Snowflake DSA-C03 Zertifizierungsprüfung besteht. Aber nun mit Pürfungsfragen zur Snowflake DSA-C03 von Itzert.com werden Sie diese Prüfung sicherlich beim ersten Versuch bestehen.
Itzert.com ist eine gute Website, wo den Kunden preisgünstige Studienmaterialien zur Zertifizierungsprüfung von hoher Qualität bietet. Unsere Fragenkataloge werden von Experten bearbeitet, die sich mit der Bereitstellung der neuesten und besten Prüfungsfragen und –antworten beschäftigen. 99,9 % Trefferrate kann Ihnen absolut helfen, die DSA-C03-Prüfung zu bestehen.
Wenn Sie nicht wissen, wie Sie sich auf die SnowPro Advanced DSA-C03 Zertifizierungsprüfung vorbereiten sollten, ist Itzert.com dann Ihre gute Studienführung. Die ausgezeichneten PDF & SOFT Prüfungsmaterialien decken fast alle wichtigen Schwerpunkte der Prüfung. Sie brauchen nur unsere Studienmaterialien innerhalb 20 bis 30 Stunden lernen.
Itzert.com wird unseren Kunden einjährigen kostenlosen Update-Service zur Verfügung stellen. Sobald sich die Prüfungsmaterialien aktualisieren, werden wir sie sofort aktualisieren und die neueste Version automatisch in Ihre Mailbox senden. Wenn Sie in der Prüfung durchfallen, sollten Sie die Scan-Kopie ihres selben Prüfungsberichts an uns senden. Nach der Bestätigung werden wir Ihnen so schnell wie möglich die volle Rückerstattung Ihres Kaufgebühren geben.
Bevor Sie Itzert.com wählen, können Sie unser kostenloses Demo downloaden, die einige Fragen und Antworten zur Snowflake DSA-C03-Prüfung enthaltet. Mit Hilfe unseren Snowflake DSA-C03 Prüfung Dumps, werden Sie Ihre Prüfung mühlos bestehen. Itzert.com wird Ihre beste Wahl sein.
Einfaches Verfahren: Es gibt nur zwei Schritte, damit Sie Ihren Kauf abschließen. Nachdem Sie bezahlen, werden wir das Produkt sofort in Ihre Mailbox schicken. Dann downloaden Sie den Anhang und Sie werden Ihr Produkt erhalten.
Einfach und bequem zu kaufen: Um Ihren Kauf abzuschließen, gibt es zuvor nur ein paar Schritte. Nachdem Sie unser Produkt per E-Mail empfängen, herunterladen Sie die Anhänge darin.
Snowflake DSA-C03 Prüfungsthemen:
| Abschnitt | Gewichtung | Ziele |
|---|---|---|
| Datenaufbereitung und Merkmalsentwicklung | 25–30 % | - Merkmalsentwicklung
|
| Bewährte Verfahren für die Datenwissenschaft in Snowflake | 15–20 % | - Sicherheit und Steuerung
|
| Generative KI und Funktionen von LLMs | 10–15 % | - Generative KI in Snowflake
|
| Modellentwicklung und maschinelles Lernen | 25–30 % | - Modellbewertung
|
| Grundlagen der Datenwissenschaft | 10–15 % | - Arbeitsablauf in der Datenwissenschaft
|
Snowflake SnowPro Advanced: Data Scientist Certification DSA-C03 Prüfungsfragen mit Lösungen
A financial institution aims to detect fraudulent transactions using a Supervised Learning model deployed in Snowflake. They have a dataset with transaction details, including amount, timestamp, merchant category, and customer ID. The target variable is 'is_fraudulent' (0 or 1). They are considering different Supervised Learning algorithms. Which of the following algorithms would be MOST suitable for this fraud detection task, considering the need for interpretability, scalability, and the potential for imbalanced classes, and what specific strategies can be employed within Snowflake to handle the class imbalance?
- A. Linear Regression, because it's computationally efficient and easy to understand, even though fraud detection is a classification problem.
- B. Support Vector Machine (SVM) with a radial basis function (RBF) kernel, as it can capture complex non-linear relationships without concern for interpretability.
- C. Naive Bayes, because it requires no hyperparameter tuning and works well on numerical data.
- D. Decision Tree or Random Forest, combined with techniques like oversampling the minority class (fraudulent transactions) within Snowflake using SQL or UDFs to balance the dataset before training. These models provide reasonable interpretability and can handle non-linear relationships effectively.
- E. K-Nearest Neighbors (KNN), because it is simple to implement and doesn't require extensive training.
Antwort: D 🗳️
Erklärung: (Nur für ITZert-Mitglieder sichtbar)
You are building a machine learning model using Snowpark for Python and have a feature column called 'TRANSACTION AMOUNT' in your 'transaction_df DataFrame. This column contains some missing values ('NULL). Your model is sensitive to missing data'. You want to impute the missing values using the median "TRANSACTION AMOUNT, but ONLY for specific customer segments (e.g., customers with a 'CUSTOMER TIER of 'Gold' or 'Platinum'). For other customer tiers, you want to impute with the mean. Which of the following Snowpark Python code snippets BEST achieves this selective imputation?
- A.

- B.

- C.

- D.

- E.
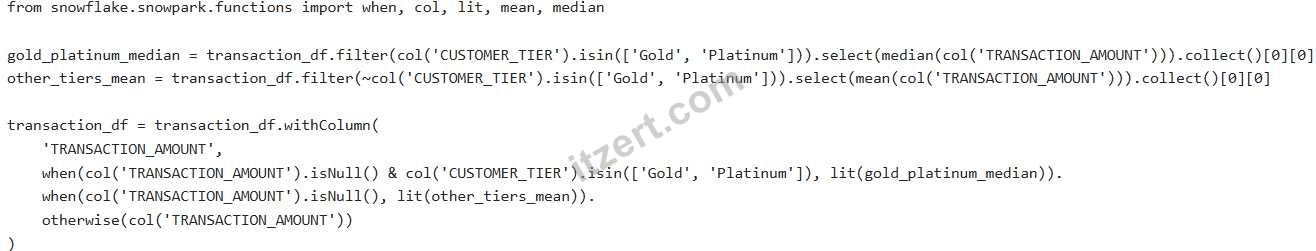
Antwort: C 🗳️
Erklärung: (Nur für ITZert-Mitglieder sichtbar)
A data science team is using Snowpark ML to train a classification model. They want to log model metadata (e.g., training parameters, evaluation metrics) and artifacts (e.g., the serialized model file) for reproducibility and model governance purposes. Which of the following approaches is the most appropriate for integrating model logging and artifact management within the Snowpark ML workflow, minimizing operational overhead?
- A. Leverage the MLflow integration within Snowpark, utilizing its ability to track experiments, log parameters and metrics, and store model artifacts directly within Snowflake stages or external storage.
- B. Employ a separate, external model management platform (e.g., Databricks MLflow, SageMaker Model Registry) and configure Snowpark to interact with it via API calls during model training and deployment.
- C. Serialize the model object to a string and store it as a VARIANT column in a Snowflake table, alongside the model metadata.
- D. Use a custom Python function to manually write model metadata to a Snowflake table and store the model file in a Snowflake stage.
- E. Only track basic model performance metrics in a Snowflake table and rely on code versioning (e.g., Git) for model artifact management.
Antwort: A 🗳️
Erklärung: (Nur für ITZert-Mitglieder sichtbar)
You are building a fraud detection model using Snowflake data'. The dataset 'TRANSACTIONS' contains billions of records and is partitioned by 'TRANSACTION DATE'. You want to use cross-validation to evaluate your model's performance on different subsets of the data and ensure temporal separation of training and validation sets. Given the following Snowflake table structure:
Which approach would be MOST appropriate for implementing time-based cross-validation within Snowflake to avoid data leakage and ensure robust model evaluation? (Assume using Snowpark Python to develop)
- A. Use 'SNOWFLAKE.ML.MODEL REGISTRY.CREATE MODEL' with default settings, which automatically handles temporal partitioning based on the insertion timestamp of the data.
- B. Utilize the 'SNOWFLAKE.ML.MODEL REGISTRY.CREATE MODEL' with the 'input_colS argument containing 'TRANSACTION DATE'. Snowflake will automatically infer the temporal nature of the data and perform time-based cross-validation.
- C. Implement a custom splitting function within Snowpark, creating sequential folds based on the 'TRANSACTION DATE column and use that with Snowpark ML's cross_validation. Ensure each fold represents a distinct time window without overlap.
- D. Create a UDF that assigns each row to a fold based on the 'TRANSACTION DATE column using a modulo operation. This is then passed to the 'cross_validation' function in Snowpark ML.
- E. Explicitly define training and validation sets based on date ranges within the Snowpark Python environment, performing iterative training and evaluation within the client environment before deploying a model to Snowflake. No built-in cross-validation used
Antwort: C 🗳️
Erklärung: (Nur für ITZert-Mitglieder sichtbar)
You are using Snowpark Pandas to prepare data for a machine learning model. You have a Snowpark DataFrame named 'transactions df that contains transaction data, including 'transaction id', 'product id', 'customer id', and 'transaction_amount'. You want to create a new feature that represents the average transaction amount per customer. However, you are concerned about potential skewness in the 'transaction_amount' and want to apply a log transformation to reduce its impact before calculating the average. Which of the following steps using Snowpark Pandas would achieve this transformation and calculation most efficiently within Snowflake?
- A. Option A
- B. Option D
- C. Option E
- D. Option C
- E. Option B
Antwort: E 🗳️
Erklärung: (Nur für ITZert-Mitglieder sichtbar)
 1320 Kundenrezensionen



Ronald -
Ich bestand die DSA-C03 Prüfung vor einigen Stunden. Die Pürfungsmaterialien von ITZert sind sher nützlich.